
If we want to teach a child how to tie their shoelaces, we usually demonstrate the process first and then let them imitate us.
Robots can learn in a surprisingly similar way.
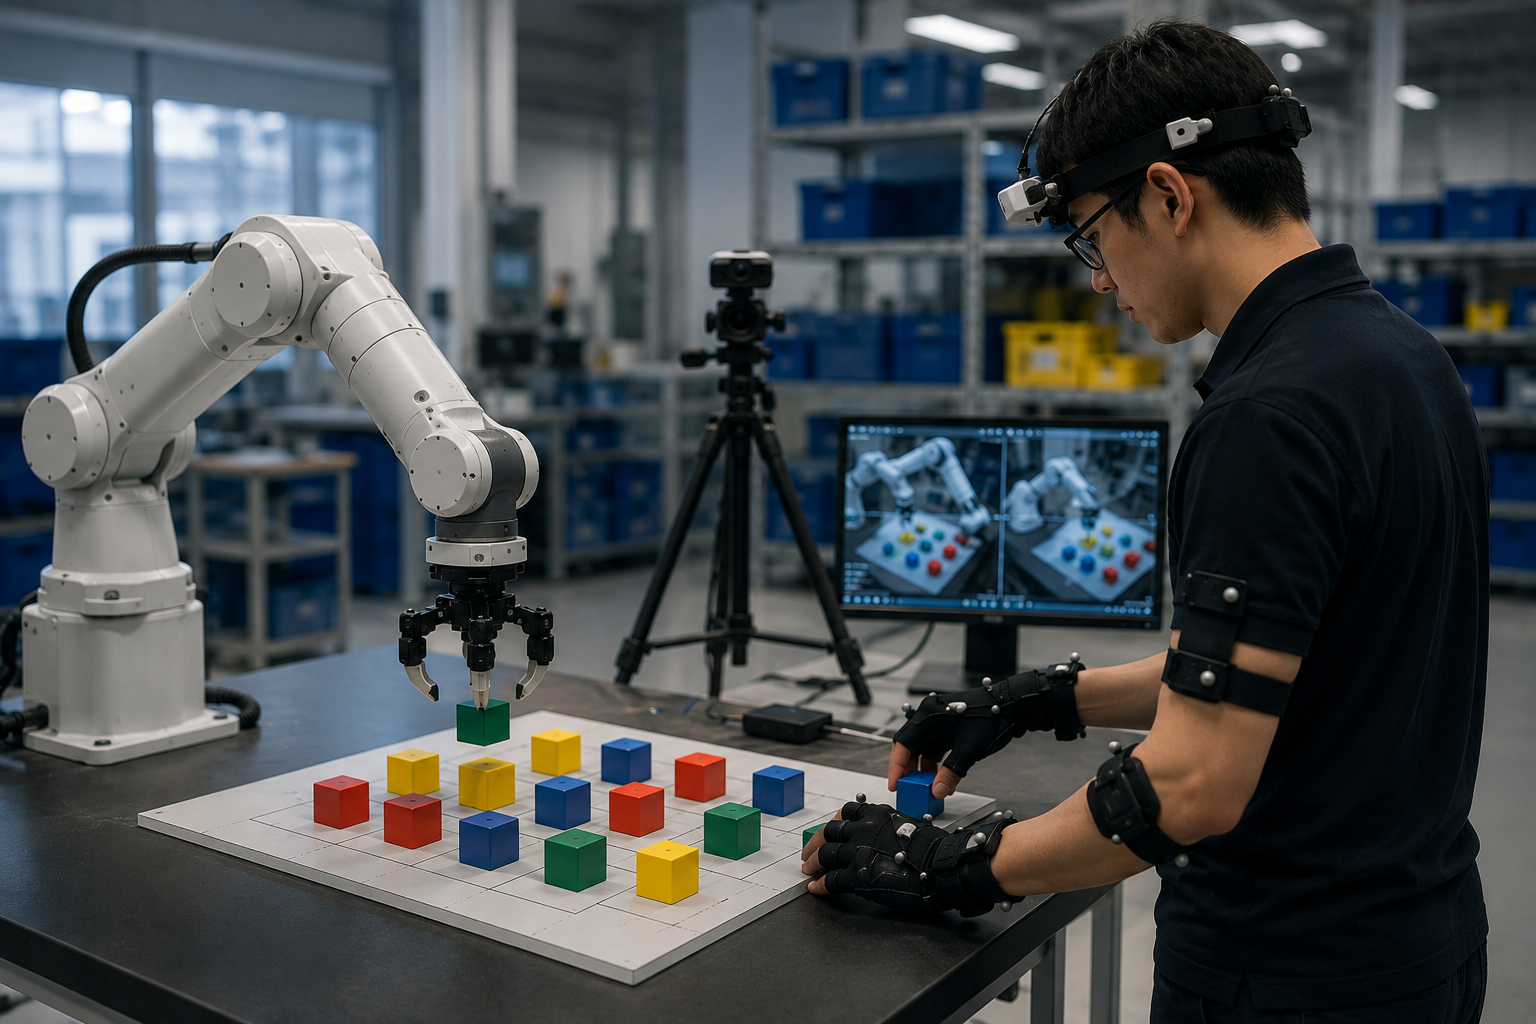
Instead of writing thousands of lines of code to define every individual movement, we can show a robot many examples of a task being performed correctly, record those demonstrations, and use the resulting data for training.
This is one of the key ideas behind Imitation Learning—learning by imitation.
Teaching Robots by Demonstration
Suppose we want to teach a robot to pick up an apple and place it into a basket.
A human operator can control the robot and perform the task repeatedly.
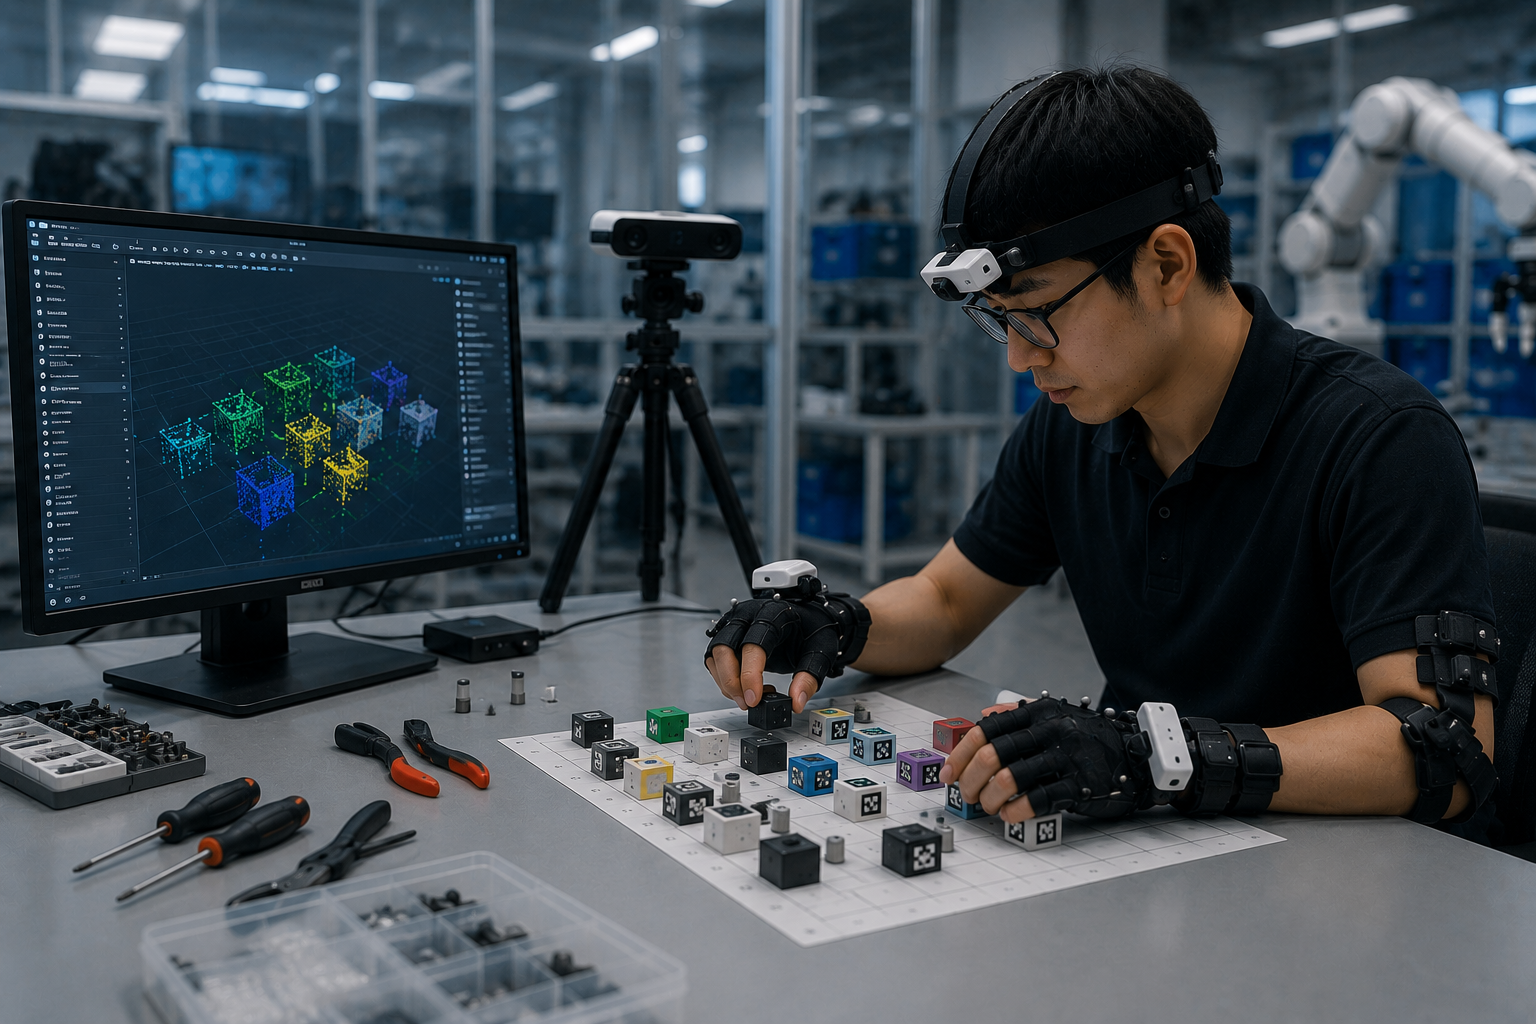
The camera records what the robot sees.
At the same time, the system can record:
- robot joint positions;
- movement directions;
- the open/closed state of the gripper;
- the timing of each action.
The process of a human directly controlling a robot remotely is commonly known as Teleoperation.
As a result, we obtain pairs of data:
What the robot sees → What the human operator tells the robot to do.
By learning from many demonstrations like these, the model can begin to predict appropriate actions when it encounters new situations. Demonstration data collected from real robots or through teleoperation is now an important part of many modern robot-training workflows.
Human Operator → Robot → Camera + Sensor → Dataset → Training → Robot Policy
There is an important term here: Policy.
In simple terms, a Policy can be thought of as the “strategy a robot uses to decide what to do.”
Input: What is the robot seeing right now?
Output: What should the robot do next?
When Robots Begin to Understand Both Vision and Language
One increasingly important direction in robotics is VLA—Vision-Language-Action.
The name may sound technical, but the basic idea is straightforward:
Vision – perceive visual information.
Language – understand instructions expressed in language.
Action – generate actions.
For example, a person might say:
“Pick up the blue water bottle and place it in the box on the right.”
The robot needs to understand the instruction, identify the correct bottle in its visual input, and finally generate a sequence of actions to complete the task.
This is how the three components—Vision, Language, and Action—come together.
A major area of research in the next generation of robotics is precisely this ability to combine perception, reasoning, and action within a unified system.
Robots Cannot Try Everything in the Real World
There is a very practical problem.
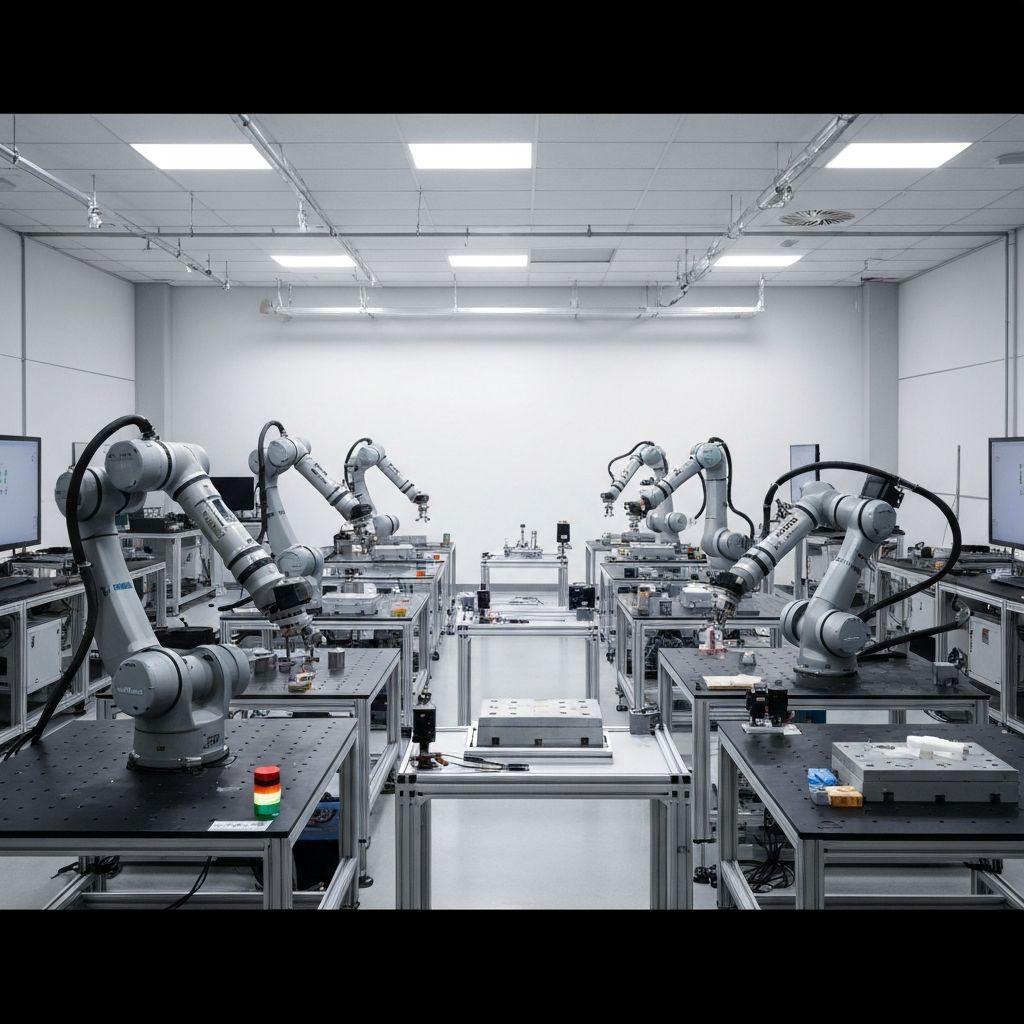
Collecting data using real robots takes time. Robots can be damaged. Objects often need to be reset after every attempt. Some potentially dangerous situations simply cannot be repeated thousands of times in the real world.
This is why robotics makes extensive use of Simulation.
Think of simulation as a “virtual world for robots.”
Inside this world, we can create robots, tables, boxes, objects, cameras, lighting conditions, and physical rules.
A robot can attempt the same task thousands of times without damaging a real machine.
REAL WORLD → DATA → SIMULATION → TRAINING → REAL ROBOT
However, simulation can never reproduce the real world with 100% accuracy.
The difference between these two environments is commonly referred to as the Sim-to-Real Gap.
One technique commonly used to reduce this gap is Domain Randomization.
Instead of creating one perfectly controlled virtual environment, the system intentionally varies factors such as lighting, colors, object positions, camera angles, and certain physical properties.
As a result, the robot must learn to operate under many different conditions rather than simply “memorizing” a single environment.
This is one of the techniques used to help policies trained in simulation transfer more effectively to real-world robots.
Real and Simulated Data Will Work Together
An important direction in Physical AI is the combination of:
Real Data + Synthetic Data + Simulation.
Real Data is collected from real-world environments.
Synthetic Data is generated using computers, simulation tools, or generative models.
Simulation provides scalable environments where robots can experiment, learn, and be evaluated without relying entirely on physical hardware.
Modern Physical AI workflows are increasingly bringing these components together to generate data, train models, evaluate performance, and transfer policies from virtual environments to real robots.
So when we see a robot successfully complete a task in just a few seconds, what we are actually seeing is only the final stage of a much longer process:
Data Collection → Training → Simulation → Testing → Evaluation → Real Robot.
A robot does not become more intelligent simply because it has a larger AI model.
It also needs better data, more experience, and a reliable process for turning what it learns inside a computer into actions that actually work in the real world.