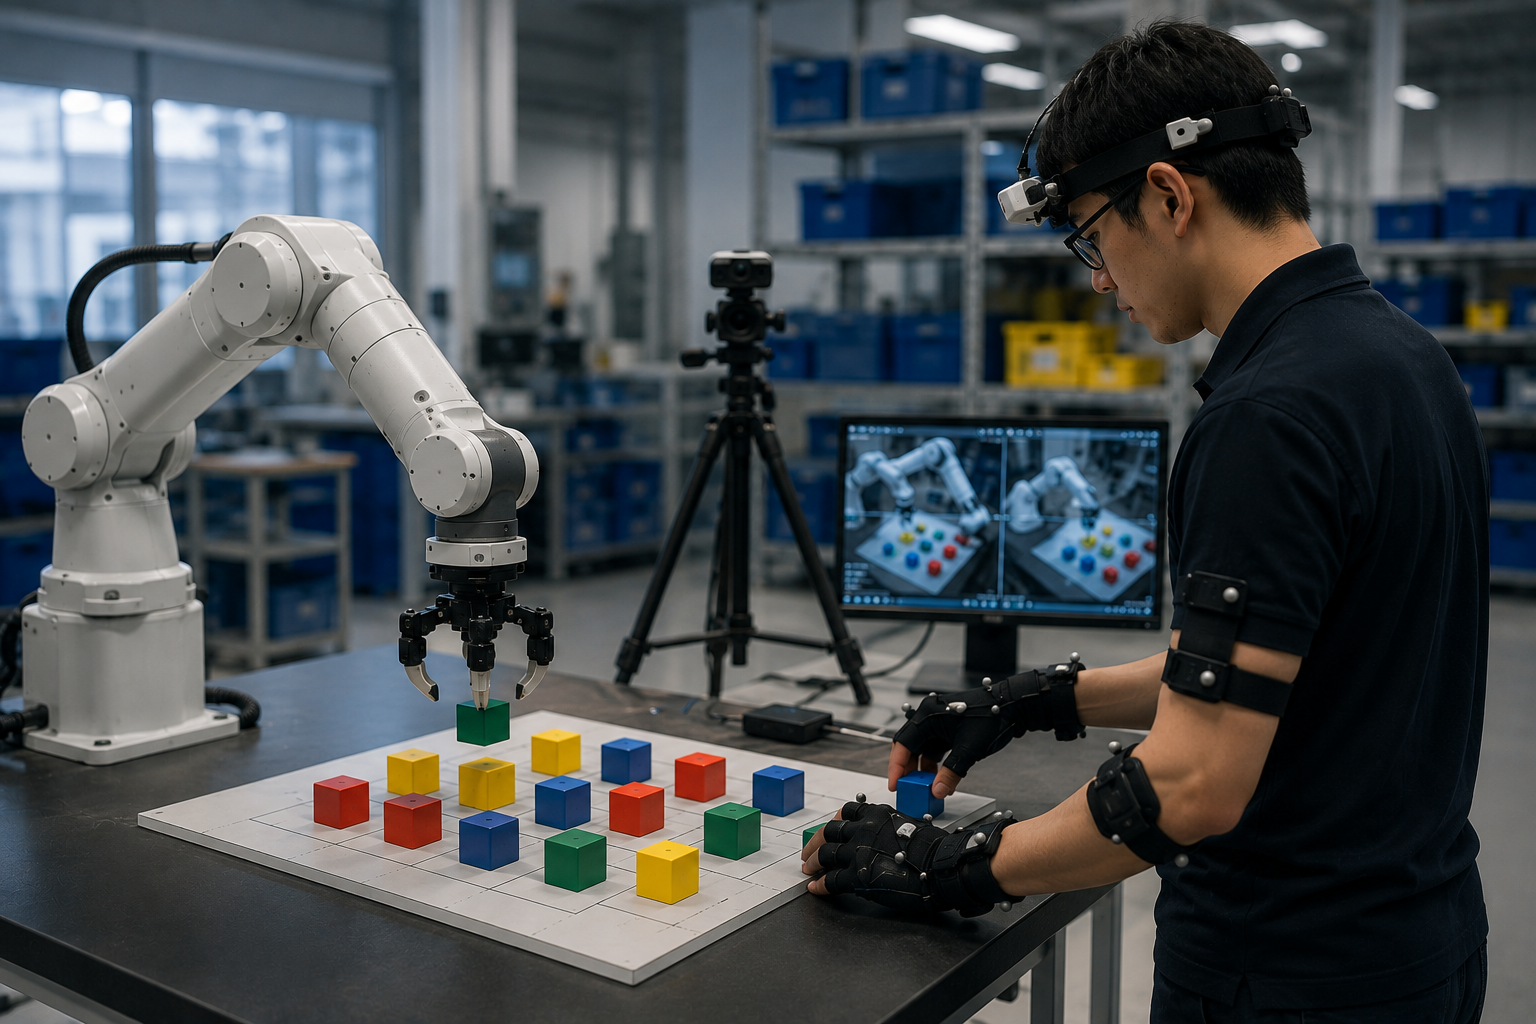
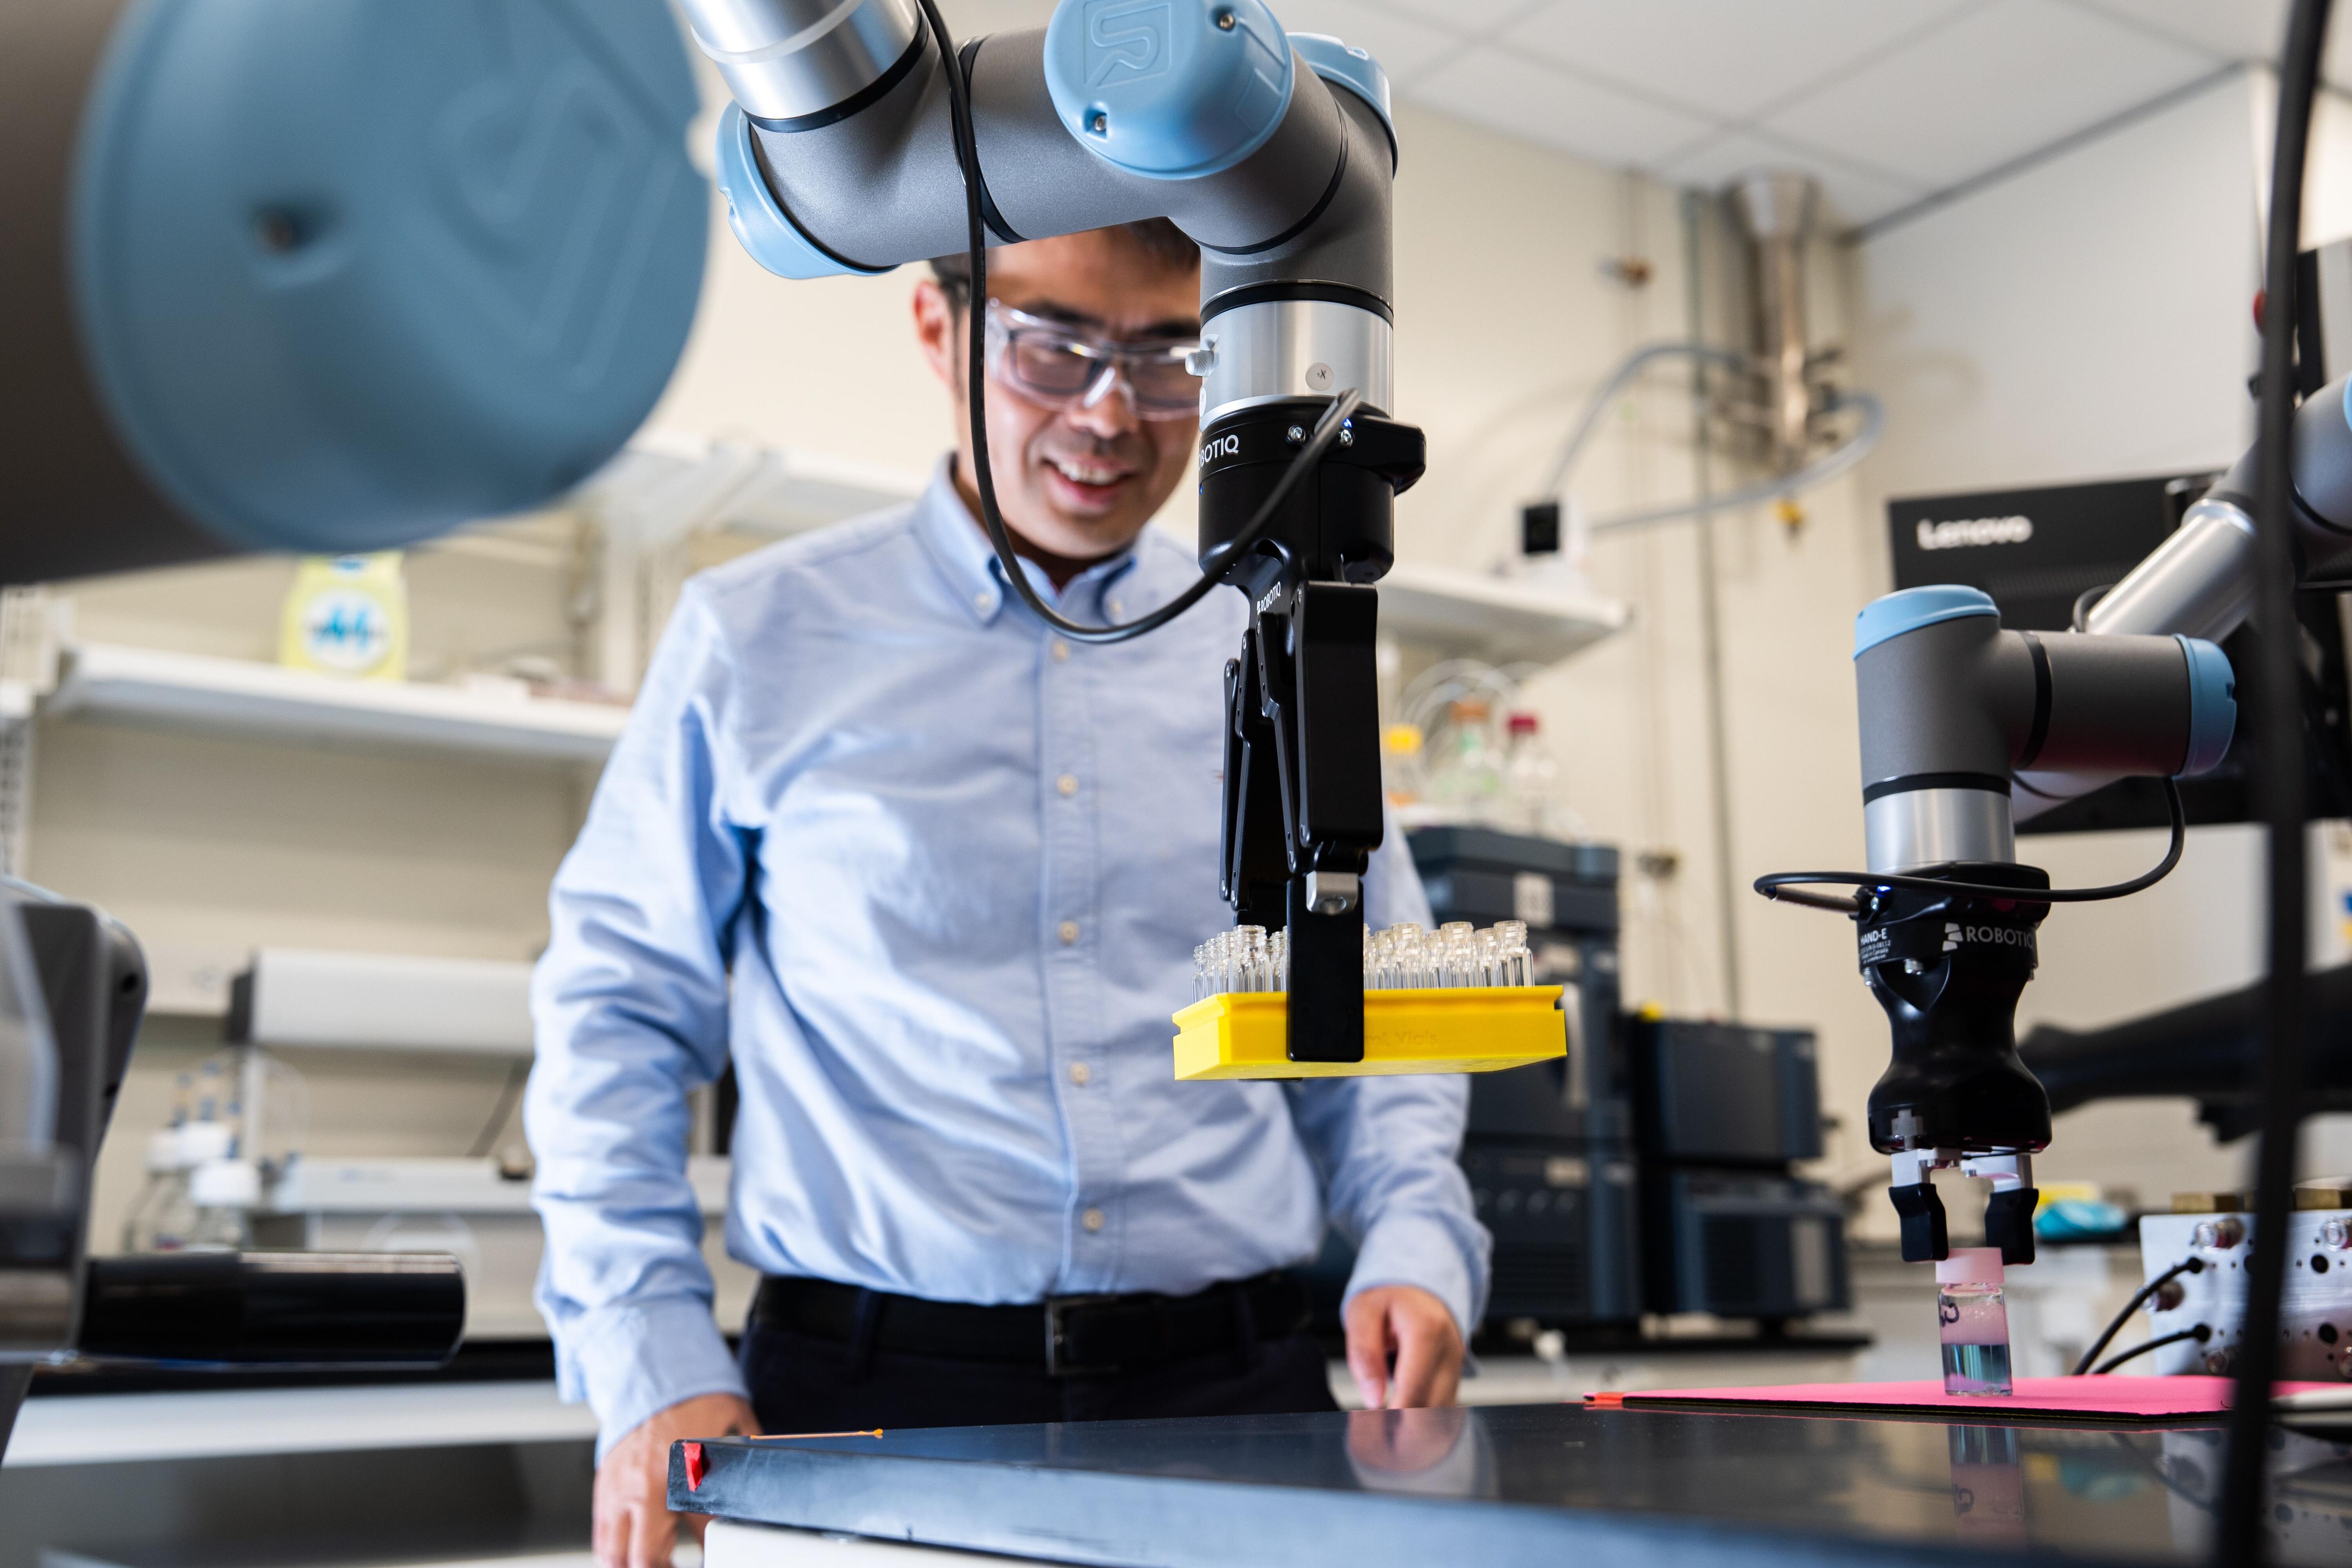

When we watch a robotic arm pick up a product from a table and place it into a box, all we see is an action that takes only a few seconds.
But within those few seconds, a continuous chain of processing is taking place across cameras, sensors, AI, and the robot control system.
A simple way to think about it is to compare it with how humans work: eyes perceive – the brain processes – the body acts.
1. Perception – Helping Robots “See”
The first thing a robot needs to understand is what exists around it.
This is commonly referred to as Perception, or simply the ability to perceive and interpret the surrounding environment.
An RGB camera captures images much like a conventional camera.
For some applications, systems also use a Depth Camera – a camera that can measure distance. This allows the system not only to recognize that “this is a box,” but also to determine how far the box is from the camera.
Depending on the task, a system may also incorporate LiDAR, force sensors, encoders, or other types of sensors.
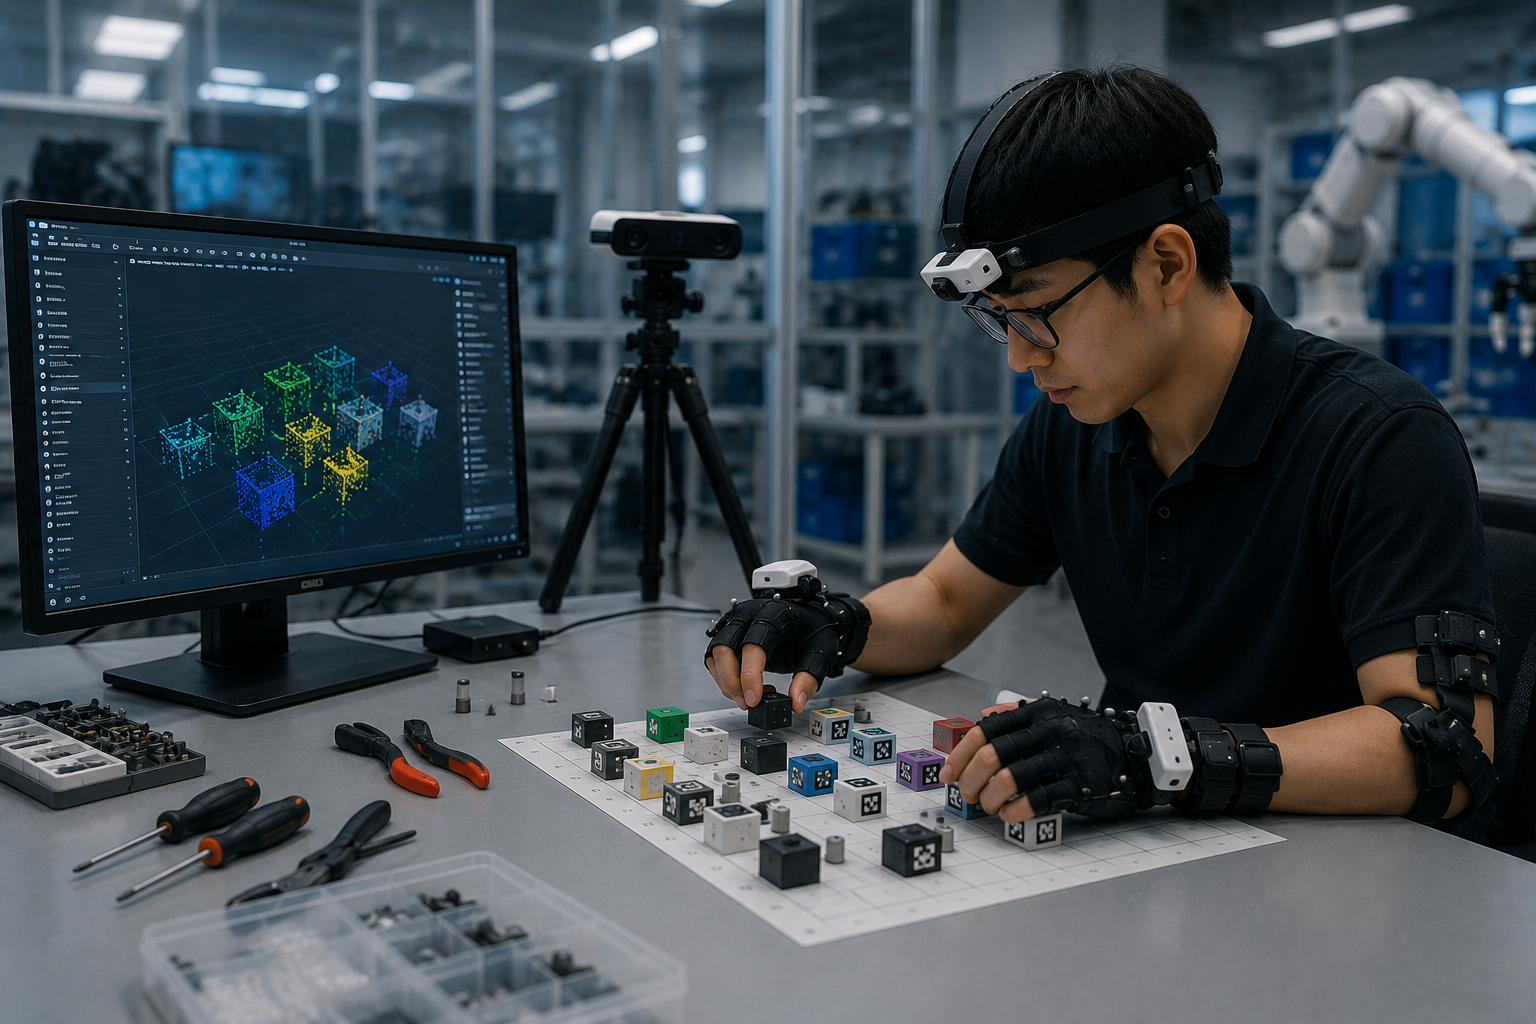
Data from multiple sensors can also be combined to create a more complete understanding of the environment. This technique is commonly known as Sensor Fusion.
Camera → RGB Image + Depth → Object Detection → 3D Position
2. AI Turns Images into Information the Robot Can Use
A camera only produces data.
AI is what enables the system to make sense of that data.
For example, if a camera sees a cup, a computer vision model may identify:
Object: Cup
Position: (x, y, z)
Orientation: the direction the cup is facing
Confidence: how certain the model is about the detection result
The three values x, y, z can be understood as the object’s coordinates in three-dimensional space.
At this point, the robot is no longer simply looking at an image.
It now has more actionable information:
“There is a cup at this position.”
3. Planning – The Robot Must Decide How to Move
Knowing where the cup is still is not enough.
The robot must calculate how to move its arm toward the object without hitting the table or other obstacles nearby.
This is the problem of Motion Planning.
The system may need to answer a sequence of questions such as:
Where is the robot now? → Where is the target? → Are there any obstacles? → What trajectory should it follow?
Once a trajectory has been calculated, the control system sends commands to the motors at each joint of the robot.
Camera/Sensor → Perception → AI Model → Planning → Robot Controller → Motor / Robot Arm
This is a simplified version of a Physical AI pipeline.
4. But Where Does the Robot Get These Capabilities?
This is where the real challenge begins.
We cannot manually program every possible situation:
“If the cup is on the left, do A.”
“If the cup is rotated 30 degrees, do B.”
“If a box is blocking the way, do C.”
The real world contains far too many variables.
That is why one of the key directions in modern robotics is to enable robots to learn from data and experience, rather than programming a separate rule for every situation.
This data can come from cameras, sensors, real robots, humans controlling robots, or simulated environments. Modern robotics workflows often combine demonstration data collection, policy training, evaluation in simulation, and only then deployment to real-world robots.
This is also why collecting data for Physical AI is not as simple as “recording a lot of video.”
The video must be connected to actions.
What does the camera see? What state is the robot in? How is the arm moving? Is the gripper – the component used to grasp objects – open or closed?
When this information is synchronized over time, it becomes a dataset that a robot can actually learn from.
And that leads to the next question:
How do robots actually learn from this data?
That is where Imitation Learning, VLA, Simulation, and Sim-to-Real come into the picture.