
When it comes to AI data collection, one of the most common questions is:
How much data do we need?
But for Physical AI, there is another question that is just as important:
What scenarios should the data cover?
10,000 videos of the same action may not be as valuable as a carefully designed dataset that covers a wide range of objects, actions, environments, and operating conditions.
That is why Saltlux Technology’s Physical AI data services are designed around the specific requirements and use cases of each project.
Design Before Collection
Before data collection begins, the problem can be broken down into several key components:
Environment – where the task takes place
Object – what the human or robot interacts with
Task – what needs to be accomplished
Action – the individual actions involved
Condition – the circumstances under which the task is performed
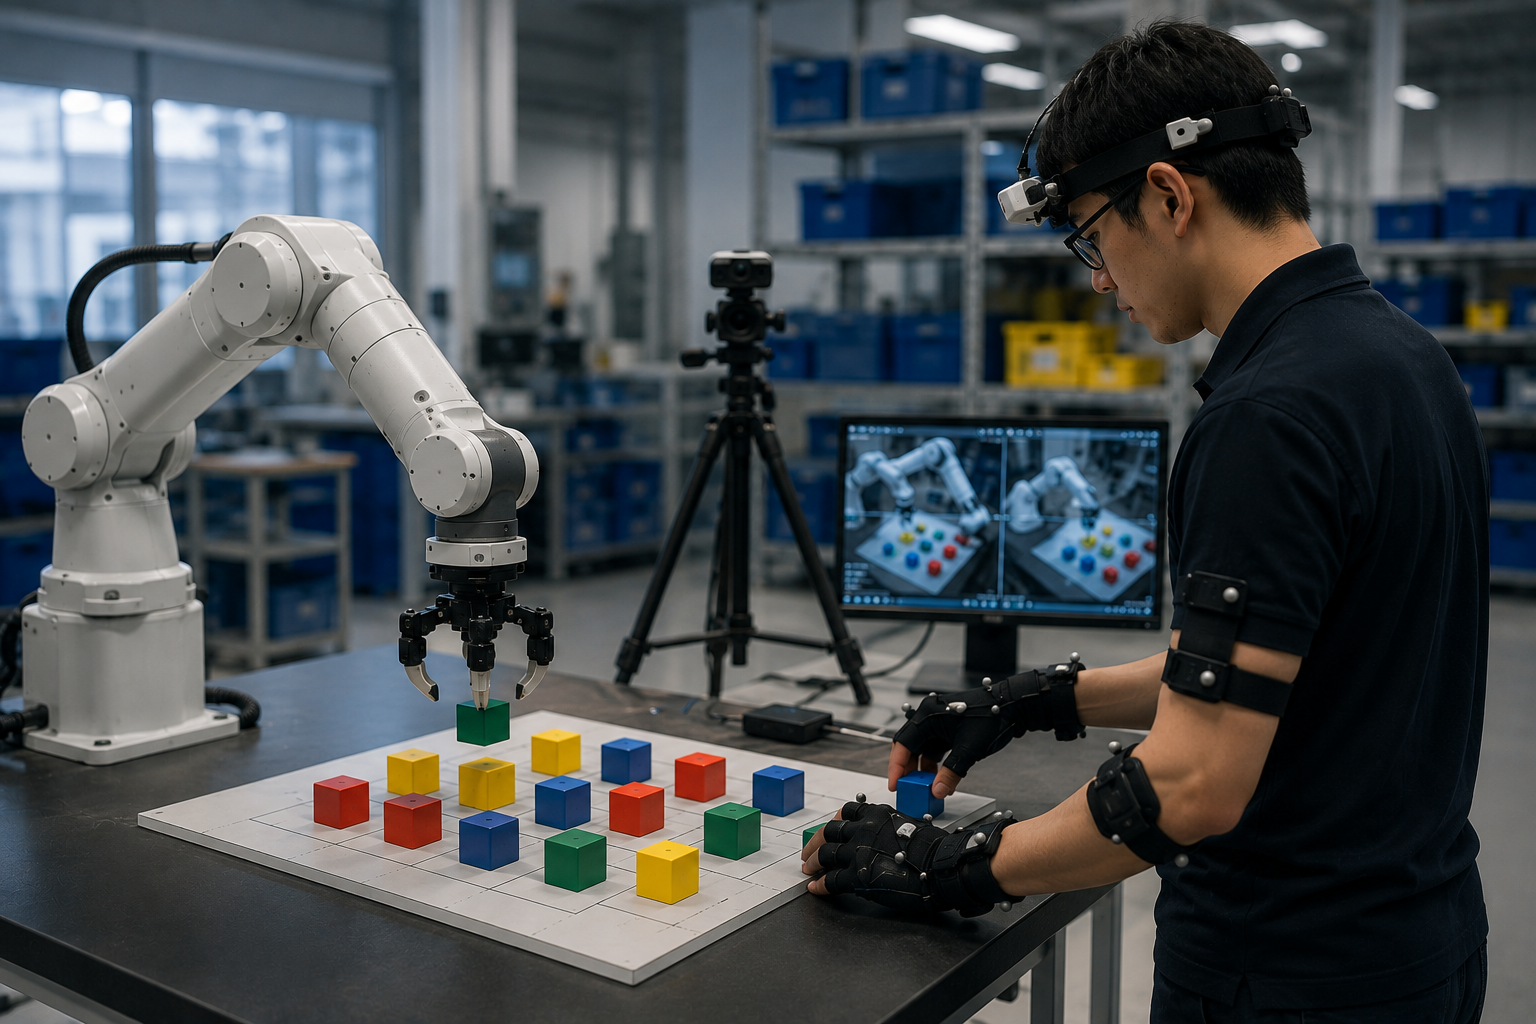
For example, even a simple grasping task can generate many different scenarios: objects may be large or small, positioned high or low, placed horizontally or vertically, or designed in ways that make them easy or difficult to grasp.
The Lab Provides Control – The Real World Provides Diversity
The two environments play different but complementary roles.
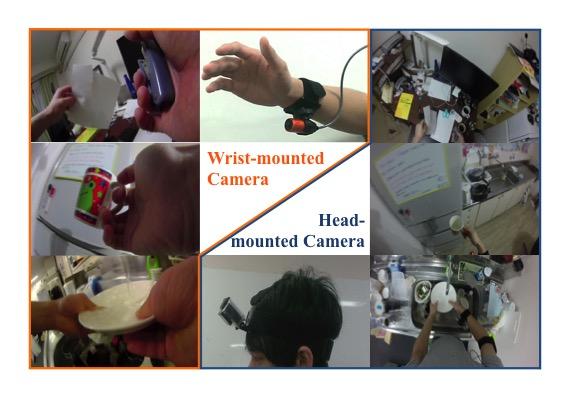
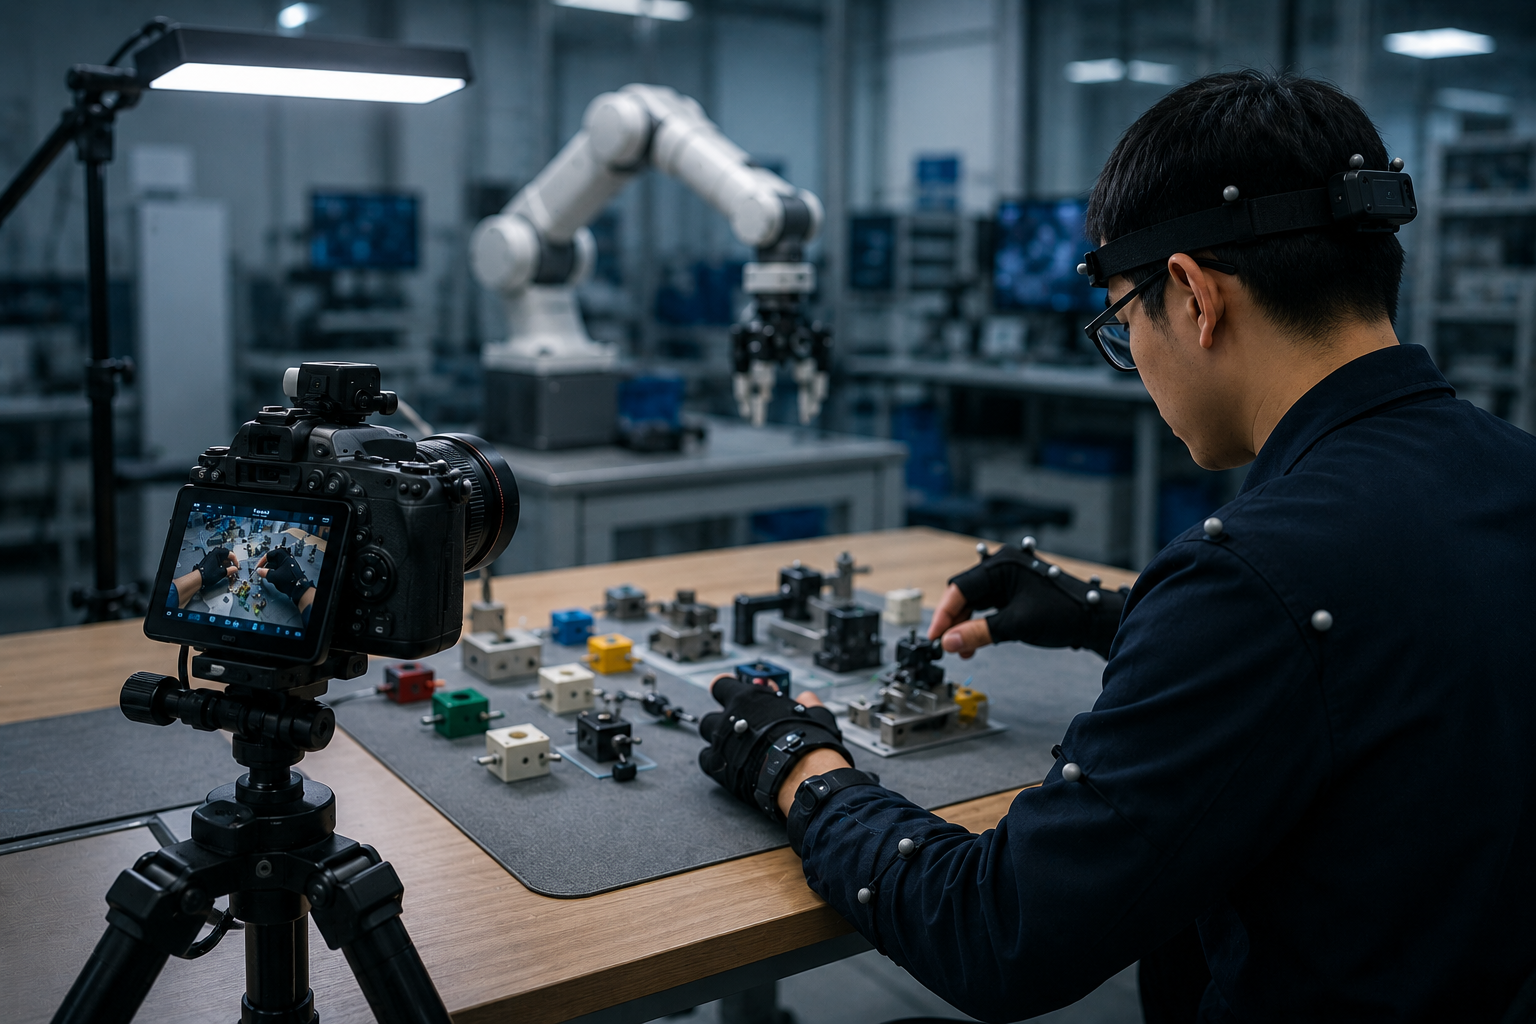
In the Lab, conditions can be controlled and repeated. This makes it suitable for testing scenarios, standardizing collection procedures, and systematically capturing specific groups of data.
Data collection can then be expanded into real-world environments.
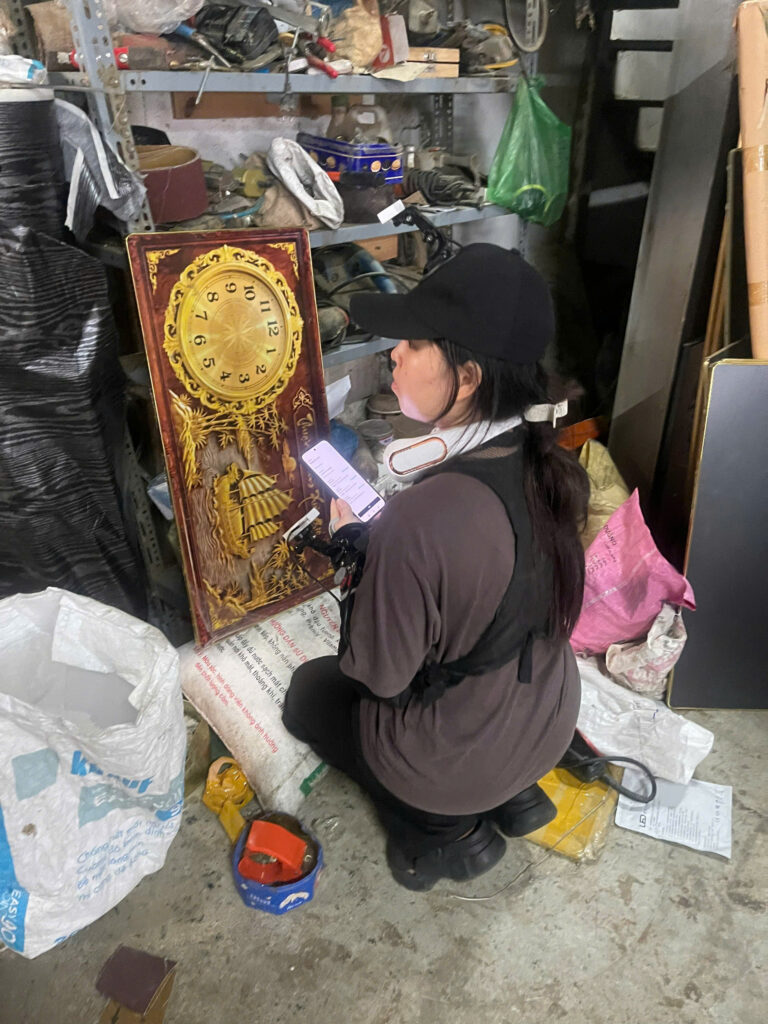
This introduces factors that are difficult to fully reproduce in the Lab: real spaces, natural lighting, a greater variety of objects, obstacles, and unexpected situations that may occur while a task is being performed.
Combining these two sources allows a dataset to achieve both control and diversity.
Data Collection Is Only the Beginning
Raw data captured from cameras and sensors is not yet a complete dataset.
Behind the collection process are additional steps such as quality inspection, data organization, synchronization across different data sources, and standardization according to project requirements.
A typical pipeline can be represented as:
Task Design
→ Lab Collection
→ Field Collection
→ Synchronization
→ Quality Control
→ Data Processing
→ Annotation
→ Dataset
Depending on the project, the structure of the dataset and the level of processing can be customized to meet specific technical and research requirements.
Data Services That Scale with the Use Case
By combining controlled Lab collection with real-world field deployment, Saltlux Technology provides custom data services for a wide range of applications, including Physical AI, Robot Learning, Computer Vision, Human Demonstration, and Human–Machine Interaction research.
Rather than simply delivering raw data, the goal is to build an end-to-end process: From the requirements of the use case → to data that AI can actually use.